GenerativeRank Review (2026): GEO Pricing, Limits & Alternatives
Bottom line
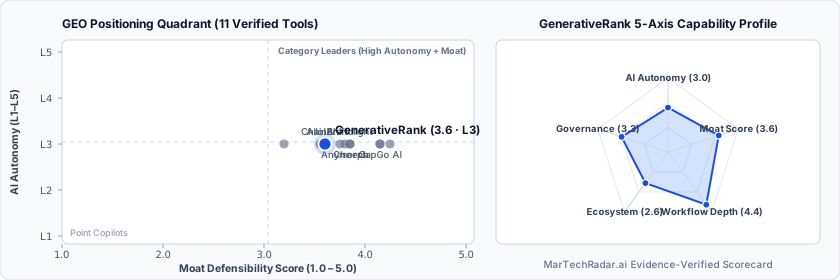
GenerativeRank is a Web SaaS tool for GEO (GEO Brand Tracking & LLM Rank Tracking) in GEO & AI SEO. Pricing: Custom / enterprise pricing. Best suited to B2B SaaS and Marketing Agencies. Editor ratings: AI autonomy L3 (conditional automation); moat score 3.6/5.0 (Proprietary moat). Fact-checked by Jiacky Lee on Oct 15, 2026.
Generative engine optimization analytics platform monitoring brand visibility, citation distribution, and recommendation share across major conversational.
GenerativeRank buyer fit verdict: when to choose vs. when to walk away
Choose GenerativeRank if (Best Fit)
- Target ICP & Stack Fit: You operate as B2B SaaS and Marketing Agencies requiring a Web SaaS deployment for GEO.
- L3 Architecture & Defensibility: Defensibility hinges on multi-agent prompt sampling topologies across LLM model families, coupled with deterministic citation parsing pipelines that map brand visibility back to indexed source corpora.
- Commercial Model Fit: Your procurement budget aligns with Custom / enterprise pricing.
Walk away from GenerativeRank if (Deal-Breakers)
- Walk away if you require transparent self-serve monthly billing or your budget ceiling is under $1,000/mo (GenerativeRank requires sales-gated custom quoting).
- Walk away if your workflow cannot tolerate model output stochasticity: Because foundational LLMs employ non-zero temperature settings and undergo unannounced weights updates, synthetic query outputs exhibit variance that requires broad statistical sampling to achieve baseline confidence.
- Walk away if inference latency and cost overhead is a deal-breaker for your team: Running deep prompt matrices across multiple commercial foundation models introduces substantial API compute overhead and token throttling bottlenecks when tracking thousands of keyword permutations.
GenerativeRank key facts & scorecard
| Pricing | Custom / enterprise pricing |
|---|---|
| Free plan | No / not disclosed |
| Delivery | Web SaaS |
| Audience | B2B SaaS, Marketing Agencies |
| AI autonomy level | L3 · Conditional automationEditor-verified |
| Moat tier & score | 3.6 / 5.0 · Proprietary moatEditor-verified |
| Funding | Bootstrapped |
| Headquarters | United States |
| Last verified |
GenerativeRank pros & cons: strengths vs. operational limitations
Pros: core strengths & capabilities
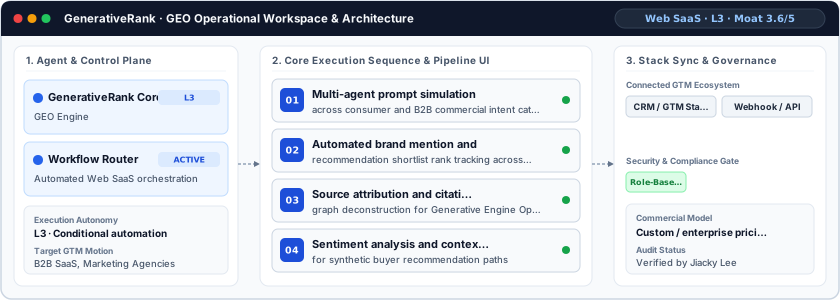
- Multi-agent prompt simulation: across consumer and B2B commercial intent categories
- Automated brand mention and: recommendation shortlist rank tracking across major conversational LLMs
- Source attribution and citation: graph deconstruction for Generative Engine Optimization audit trails
- Sentiment analysis and context extraction: for synthetic buyer recommendation paths
Cons: operational limitations & risks
- Model Output Stochasticity: Because foundational LLMs employ non-zero temperature settings and undergo unannounced weights updates, synthetic query outputs exhibit variance that requires broad statistical sampling to achieve baseline confidence.
- Inference Latency and Cost Overhead: Running deep prompt matrices across multiple commercial foundation models introduces substantial API compute overhead and token throttling bottlenecks when tracking thousands of keyword permutations.
- Citation Attribution Obfuscation: Closed-source conversational interfaces frequently mask their retrieval-augmented generation sources, limiting the system's ability to isolate exact origin indices when models hallucinate citations.
GenerativeRank TCO & deal-breaker stress test
Simulate 12-month stepped TCO, hidden cost multipliers, contract lock-in exposure, and stack failure modes using only facts verified by Jiacky Lee on · Capture SHA 22856ff0.
GenerativeRank triggers high-severity friction under your 5-seat / $800/mo constraints. Benchmark the verified subtrack alternatives below before committing.
| Plan / Tier | Verified Rate | Scale Fit | Scope & Quota Notes |
|---|---|---|---|
| Enterprise / Custom | Custom quote | 15–50+ seats (Enterprise SLA) | Sales-negotiated annual contract for custom volume, SSO/RBAC governance, and dedicated SLA. |
- Moat Score
- 3.6 / 5.0
- AI Autonomy
- L3
- Free Tier / Trial
- None disclosed
Triggered audit signals & failure modes
- Opaque Enterprise Quoting vs. SMB/Mid-Market BudgetVerified Pricing Ledger
GenerativeRank does not disclose a public self-serve floor (Custom / enterprise pricing). Buyers with a $800/mo cap face high sales-qualification friction.
- Sales-Gated Contract TermsFact-checked by Jiacky Lee
GenerativeRank provides its platform under an enterprise software-as-a-service licensing structure. Commercial pricing is available on request through tailored enterprise sales quotes based on organizational scale and seats.
- Primary Operational Bottleneck: Inference Latency and Cost OverheadAudit by Jiacky Lee
Running deep prompt matrices across multiple commercial foundation models introduces substantial API compute overhead and token throttling bottlenecks when tracking thousands of keyword permutations.
Hidden TCO Multipliers & Quota Gates
- Credit & Usage Burn Multiplier: Automated workflows consume metered credits/usage quotas; multi-step enrichment, voice minutes, or high-frequency agent runs can trigger mid-cycle top-up packs.
- Model Output Stochasticity: Because foundational LLMs employ non-zero temperature settings and undergo unannounced weights updates, synthetic query outputs exhibit variance that requires broad statistical sampling to achieve baseline confidence.
- Inference Latency and Cost Overhead: Running deep prompt matrices across multiple commercial foundation models introduces substantial API compute overhead and token throttling bottlenecks when tracking thousands of keyword permutations.
When to Walk Away & Negotiation Levers
- Walk away if you require transparent self-serve monthly billing or your budget ceiling is under $1,000/mo (GenerativeRank requires sales-gated custom quoting).
- Walk away if your workflow cannot tolerate model output stochasticity: Because foundational LLMs employ non-zero temperature settings and undergo unannounced weights updates, synthetic query outputs exhibit variance that requires broad statistical sampling to achieve baseline confidence.
- Walk away if inference latency and cost overhead is a deal-breaker for your team: Running deep prompt matrices across multiple commercial foundation models introduces substantial API compute overhead and token throttling bottlenecks when tracking thousands of keyword permutations.
- Demand a 30- to 60-day paid pilot opt-out clause in the GenerativeRank order form before signing a 12-month enterprise commitment.
- Require a sandbox proof-of-concept testing model output stochasticity against your live CRM/data schema before annual sign-off.
Ask a custom procurement or TCO stress-test question about GenerativeRank
Lower 5-seat floor (~$24/mo vs. Custom Quote) · Transparent self-serve entry without mandatory annual lock-in
Lower 5-seat floor (~$799/mo vs. Custom Quote) · Transparent self-serve entry without mandatory annual lock-in
GenerativeRank moat & subtrack positioning
Defensibility hinges on multi-agent prompt sampling topologies across LLM model families, coupled with deterministic citation parsing pipelines that map brand visibility back to indexed source corpora.
Editorial review
Fact-checked by Jiacky Lee (Managing Editor, AI Autonomy & Moat Methodology) on .
Background
Architected to solve the attribution vacuum created as enterprise search shifts from static search engine results to generative response models, GenerativeRank operates from the United States to deliver continuous visibility intelligence across major conversational interfaces. The platform targets corporate digital marketing directors, search specialists, and enterprise brand strategists seeking structured intelligence regarding how large language models represent their products. By addressing generative engine optimization, GenerativeRank provides analytics to detect brand omission, source citation paths, and competitive displacement across multi-turn artificial intelligence interactions.
How GenerativeRank works
At an operational Level 3 autonomy tier, GenerativeRank executes automated multi-agent synthetic probing routines across models such as OpenAI ChatGPT, Anthropic Claude, and Perplexity. The data ingestion pipeline schedules prompt permutations simulating distinct buyer personas, executing queries through programmatic inference endpoints. Its algorithmic framework parses raw unstructured outputs to log mention presence, rank position in comparative shortlists, and contextual sentiment. Simultaneously, the citation extraction engine resolves outbound reference links and source domains, compiling time-series share-of-voice indices that trace back to the underlying retrieved knowledge corpus.
Limitations
Operational considerations and platform boundaries include:
- Model Output Stochasticity: Because foundational LLMs employ non-zero temperature settings and undergo unannounced weights updates, synthetic query outputs exhibit variance that requires broad statistical sampling to achieve baseline confidence.
- Inference Latency and Cost Overhead: Running deep prompt matrices across multiple commercial foundation models introduces substantial API compute overhead and token throttling bottlenecks when tracking thousands of keyword permutations.
- Citation Attribution Obfuscation: Closed-source conversational interfaces frequently mask their retrieval-augmented generation sources, limiting the system's ability to isolate exact origin indices when models hallucinate citations.
GenerativeRank pricing
GenerativeRank provides its platform under an enterprise software-as-a-service licensing structure. Commercial pricing is available on request through tailored enterprise sales quotes based on organizational scale and seats. Contracts scale based on targeted query volumes, the frequency of model polling intervals, and the number of monitored competitor brands across regional endpoints.
How GenerativeRank compares
Within the generative engine optimization category, GenerativeRank competes alongside platforms including Anymorph, AthenaHQ, and Brandlight. While AthenaHQ targets executive-level reputation dashboards and Brandlight emphasizes digital public relations citation mapping, GenerativeRank prioritizes granular persona simulations and deep programmatic shortlisting analytics. Anymorph centers on tactical SERP-to-LLM bridge mechanics. GenerativeRank suits mid-market to enterprise consumer and software brands requiring programmatic visibility monitoring across high-value buyer consideration queries. It is best suited for enterprise marketing teams and growth practitioners seeking disciplined workflow orchestration.
Frequently asked questions about GenerativeRank
How much does GenerativeRank cost and does it require a custom enterprise quote?
Published pricing summary for GenerativeRank: Custom / enterprise pricing. A permanent free plan is not disclosed for GenerativeRank. GenerativeRank provides its platform under an enterprise software-as-a-service licensing structure. Commercial pricing is available on request through tailored enterprise sales quotes based on organizational scale and seats.
How does GenerativeRank work and how autonomous is its AI architecture?
Generative engine optimization analytics platform monitoring brand visibility, citation distribution, and recommendation share across major conversational. Within GEO (GEO Brand Tracking & LLM Rank Tracking), MarTechRadar rates its execution architecture at L3 · Conditional automation with a verified Moat Score of 3.6 / 5.0 (Proprietary moat). Defensibility hinges on multi-agent prompt sampling topologies across LLM model families, coupled with deterministic citation parsing pipelines that map brand visibility back to indexed source corpora.
What are the main limitations of GenerativeRank and when should buyers walk away?
Based on our editorial technical audit, key operational considerations and boundaries for GenerativeRank include: (1) Model Output Stochasticity: Because foundational LLMs employ non-zero temperature settings and undergo unannounced weights updates, synthetic query outputs exhibit variance that requires broad statistical sampling to achieve baseline confidence. (2) Inference Latency and Cost Overhead: Running deep prompt matrices across multiple commercial foundation models introduces substantial API compute overhead and token throttling bottlenecks when tracking thousands of keyword permutations. (3) Citation Attribution Obfuscation: Closed-source conversational interfaces frequently mask their retrieval-augmented generation sources, limiting the system's ability to isolate exact origin indices when models hallucinate citations. Primary procurement walk-away rule: Walk away if you require transparent self-serve monthly billing or your budget ceiling is under $1,000/mo (GenerativeRank requires sales-gated custom quoting).
What integrations, compliance certifications, and contract terms apply to GenerativeRank?
Key TCO multiplier to watch: Credit & Usage Burn Multiplier (Automated workflows consume metered credits/usage quotas; multi-step enrichment, voice minutes, or high-frequency agent runs can trigger mid-cycle top-up packs.) Before signing a contract, procurement teams should demand a 30- to 60-day paid pilot opt-out clause in the GenerativeRank order form before signing a 12-month enterprise commitment.
What are the best GenerativeRank alternatives and head-to-head competitors in 2026?
Top fact-checked alternatives to GenerativeRank in GEO (GEO Brand Tracking & LLM Rank Tracking) include Brand UP (Custom / enterprise pricing), EntityMap (Custom / enterprise pricing), GeoRank (Custom / enterprise pricing), Perplexity Tracker (Custom / enterprise pricing). Within the generative engine optimization category, GenerativeRank competes alongside platforms including Anymorph, AthenaHQ, and Brandlight.
Verified sources & evidence trail
- Official product domain: https://generativerank.com
- Commercial pricing verification: Verified against official vendor pricing policy (Custom / enterprise pricing)
- Editorial audit sign-off: Fact-checked by Jiacky Lee on under the MarTechRadar Evidence-Ledger Protocol.